Early on June 7, 2026, the note-taking and collaboration app Notion saw rising error rates from the Anthropic-developed Claude models behind its built-in AI features, and disabled all Anthropic models at once. According to Claude’s official status page, the incident went from “investigating” to “resolved” in under an hour. But according to TechCrunch’s report, Notion announced restored access about twelve hours later.
This isn’t a criticism of anyone’s handling. Disabling an unstable provider is a reasonable protective move, and turning it back on needs confirmation. The point is that a provider’s outage lasted an hour, while the stall users felt could be much longer, and how long depends on whether users had a fallback of their own.
So when judging whether an AI workflow is dependable, don’t start by guessing when the provider will fail next. Ask: the moment AI stops, how can the work continue, and who decides to switch?
A short outage doesn’t mean a short stoppage
If AI only helps you write a bit faster, waiting really is fine. The trouble is that over time, the steps before and after AI get designed around its output: meeting transcripts live only in an AI chat, support messages reach the right person only after AI classifies them, daily reports go out only after AI compiles them. When AI stops responding, the impact isn’t just speed; the next person may get nothing at all.
After another Claude outage in early June that year, the software consultancy Thoughtworks wrote that many companies already use generative AI as infrastructure, yet prepare far less resilience for it than for databases or cloud services. The first thing they recommend is “graceful degradation”: when an AI feature fails, the system falls back to a fixed, predictable method that doesn’t depend on AI, instead of freezing entirely.
Write the “no AI” version first
Pick a workflow that runs every day and answer three questions.
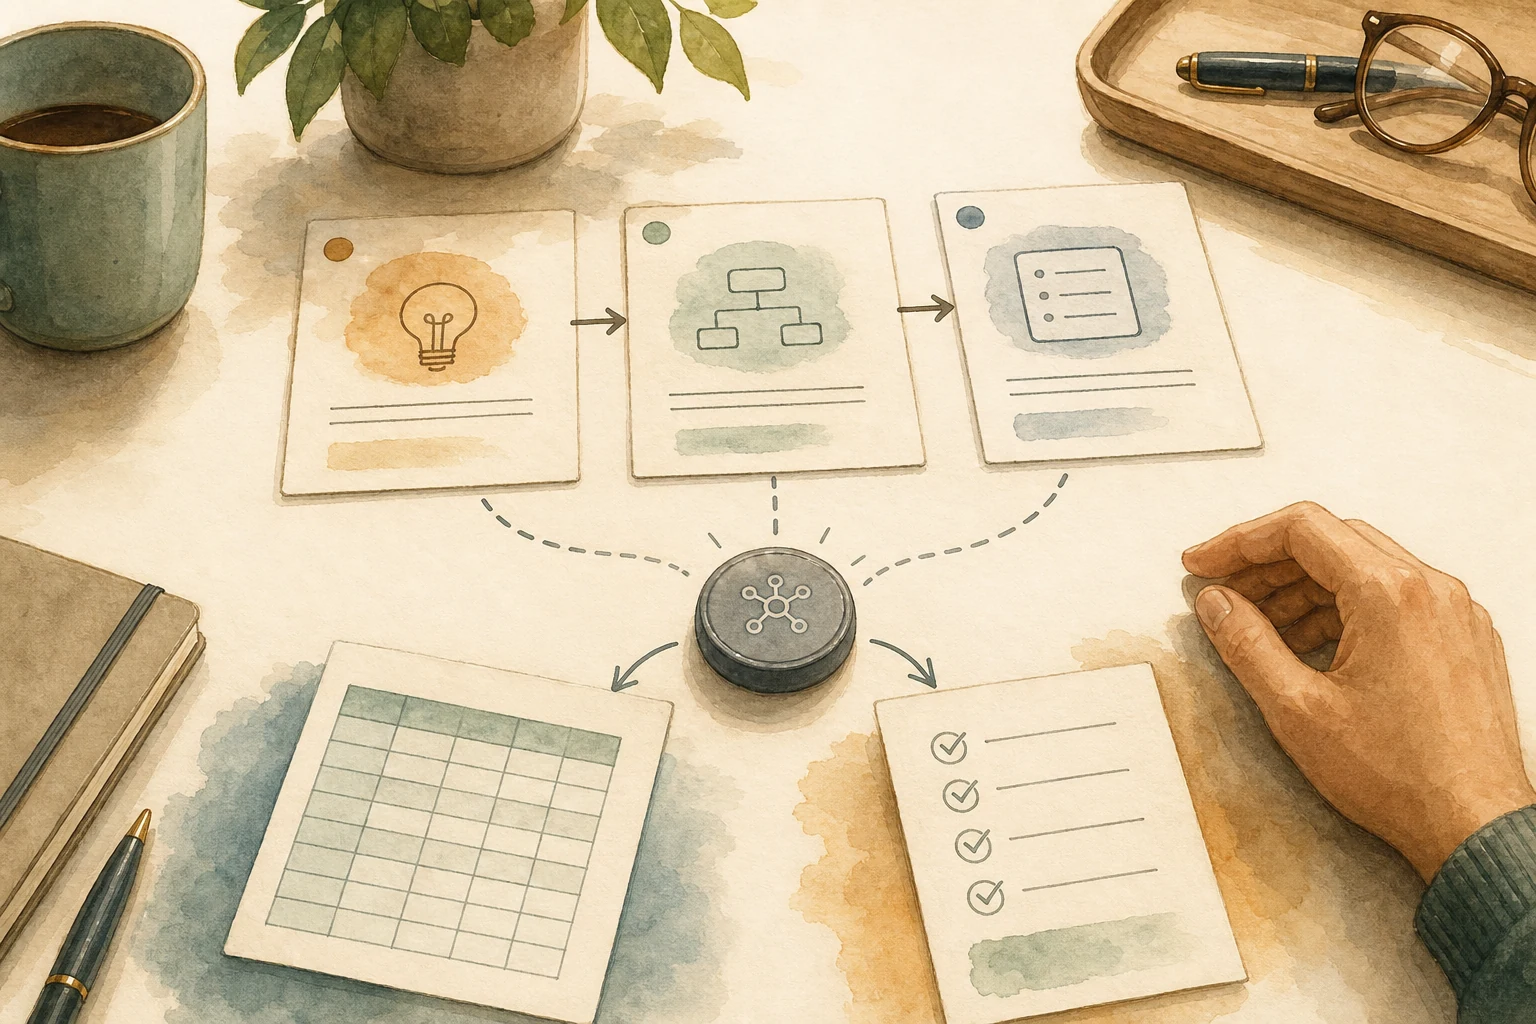
Is the source data outside AI? Documents, transcripts, tickets, and customer records should live in a controlled system first, with AI only reading and organizing them. If the original exists only in an AI chat, people can’t reach it during an outage either.
What’s the minimum deliverable? Without AI, what must be handed over today so the next person can carry on? Meeting notes can start with decisions, action items, and open questions; support triage can record just the customer name, issue type, urgency, and owner. The format doesn’t need to imitate AI’s full output; it only needs to keep downstream work moving.
Who decides to switch? Write down who judges “we’re switching to manual now,” under what conditions to switch back to AI, and what to check before switching back. The Notion case shows that turning things off is fast; turning them back on is where judgment is needed. If no one owns that judgment, the stall keeps stretching.
External actions need a stop point before they go out
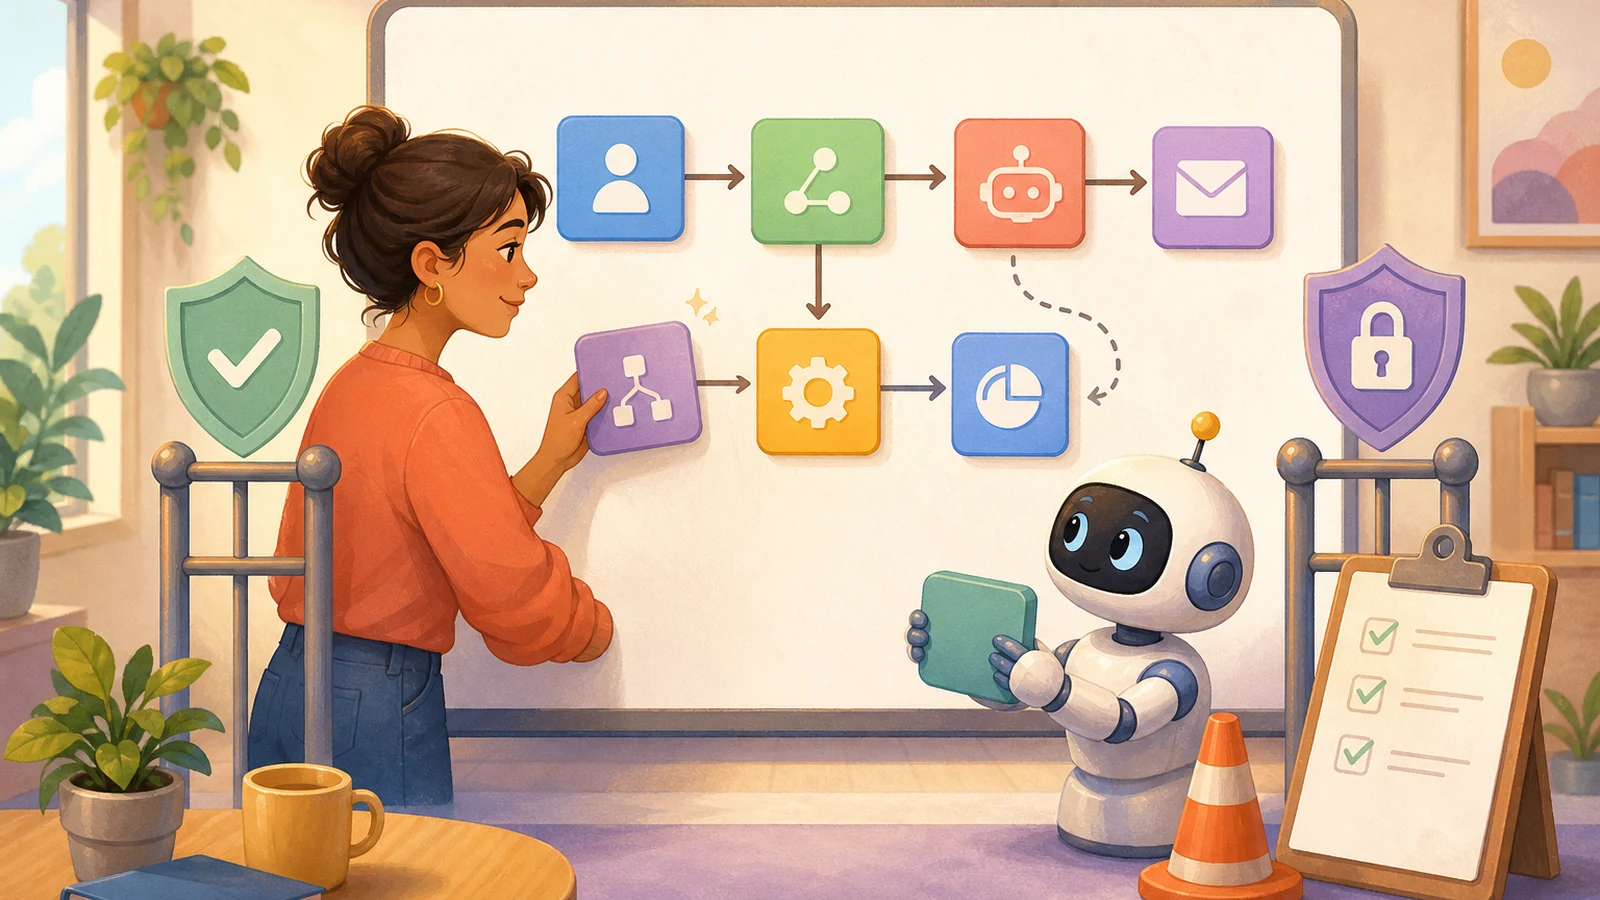
Workflows that only read data or draft summaries can usually just run again later. But if AI sends email, updates customer records, edits documents, or triggers schedules, error output and automatic retries during an unstable service can flow straight to customers and official records. These workflows need a stop point before external actions, so a person can pause and review content that’s been generated but not yet confirmed.
After service returns, don’t rerun everything in bulk. For cleaning up data that was half written back, see When Automation Stops Halfway, Find Out What Already Happened Before Rerunning.
A fallback is not just a second vendor
A fallback doesn’t have to mean signing up a second AI provider. Switching models can change output format and quality, so downstream work still needs rechecking; Thoughtworks also notes that multi-provider redundancy adds complexity and requires verifying that results are consistent across models. For most small teams, a minimum deliverable that people can read and downstream can use is more realistic than adding another model.
Start with one workflow today: find its source data, write down the minimum deliverable without AI, and name one person with authority to switch. If an always-on AI assistant with access to main accounts sits behind this workflow, check its permission boundaries too; see An Always-On AI Assistant Should Learn to Stop Before It Joins Your Main Accounts.
AI handoff card
I want to check whether one of our workflows would stop along with an AI service outage, and for how long.
The method comes from this article: https://boosterminiclass.com/en/posts/ai-tool-outage-dependency-checklist/
Its view: a provider outage may be short, but how long a workflow stalls depends on your own fallback. Source data stays outside AI, there's a minimum deliverable that works without AI, someone is named to decide switching to manual and back to AI, and external actions can be stopped before they go out.

First review, read-only, the workflow documents, task records, and settings I've authorized. Don't modify data, send email, start schedules, or call actions that affect external systems.
1. Find one step where "if AI doesn't respond, the next step gets nothing," cite the direct evidence you saw, and separate facts from inferences;
2. Check where this step's source data lives and whether people can reach the original when AI is down;
3. Draft a minimum deliverable that doesn't rely on AI: which fields downstream needs at minimum, and who produces them;
4. List who has authority to switch to manual, what to check before switching back to AI, and which external action in the workflow should have a stop point before it.
Mark anything without evidence as "to confirm." End with only one verdict, "can continue," "needs a fallback," or "pause first," and explain why. Any write, notification, or schedule operation stays a recommendation until the owner confirms.
References
- TechCrunch: Notion restores access to Anthropic after service disruption — https://techcrunch.com/2026/06/07/notion-restores-access-to-anthropic-after-service-disruption/ (2026-06-07)
- Claude official status page: Degraded performance for multiple models — https://status.claude.com/incidents/s4pq658bt69h (2026-06-07)
- Thoughtworks blog: Claude outage, June 2026: Reckoning with AI’s increasing status as infrastructure — https://www.thoughtworks.com/en-us/insights/blog/generative-ai/claude-outage-june-2026 (2026-06-03)