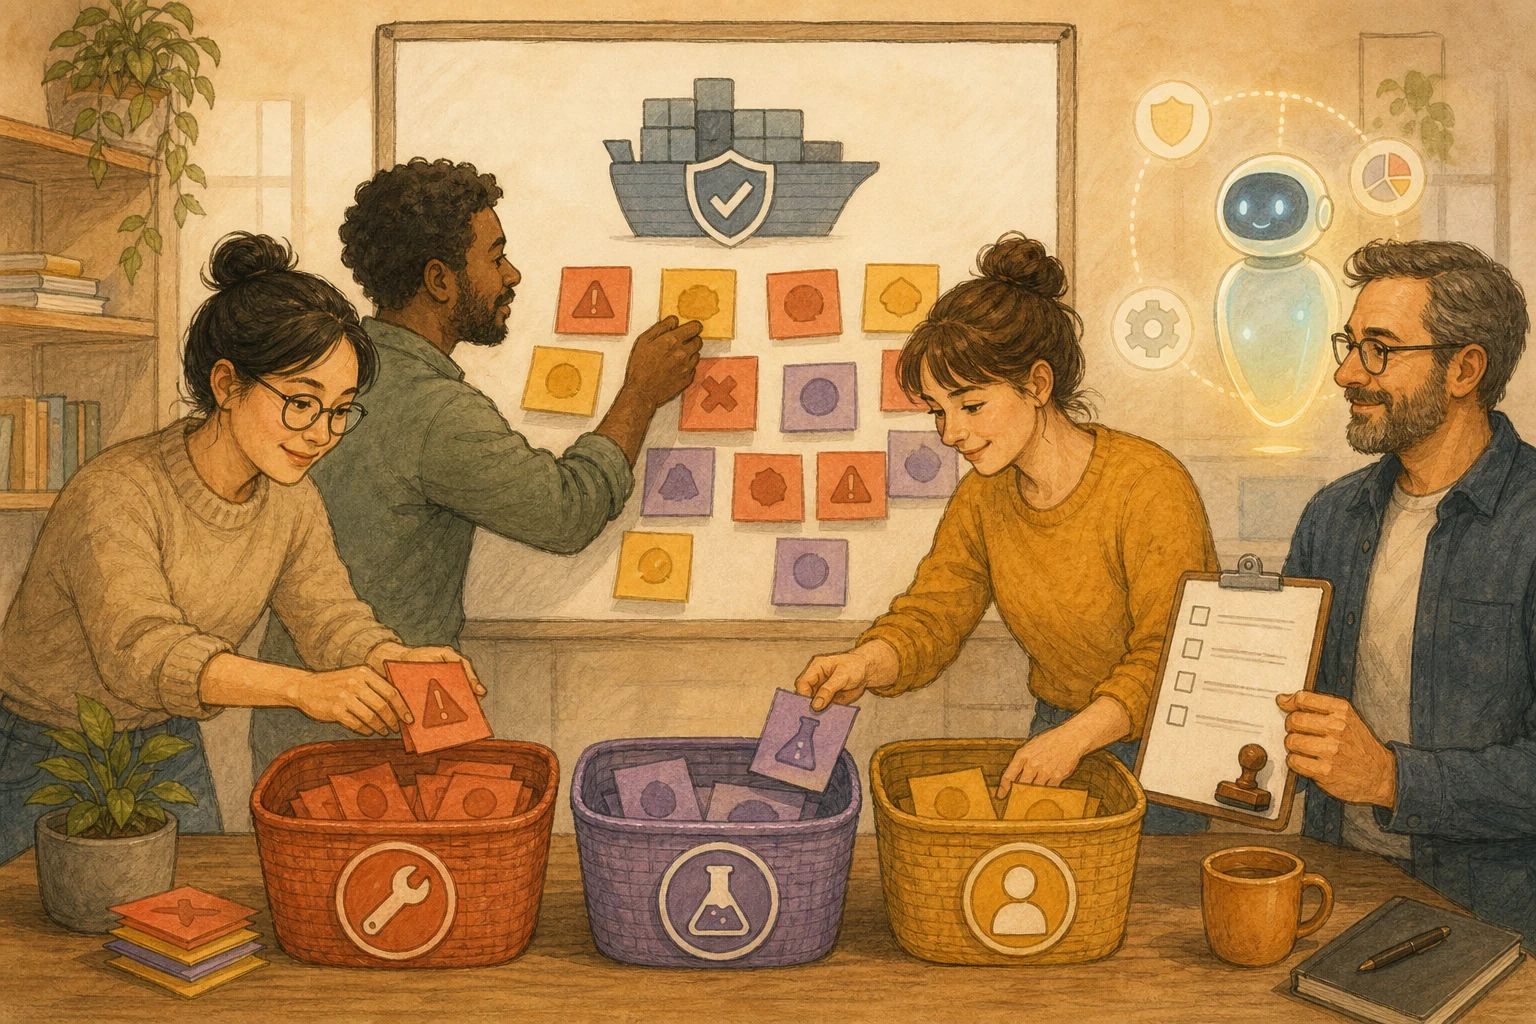
A security scan delivers 300 alerts at once. The easy approach is to work down from the highest score. But suppose the top item scores 9.8 and sits in a package used only for testing, one that never ships in the production service. Meanwhile a 6.5 ranked somewhere past one hundred is in the library that processes user-uploaded images, right behind the public website’s upload feature, and it’s already on the “known exploited” list. Queue by score, and the genuinely urgent one sits in the middle of the list for days.
A scan score measures how severe a vulnerability is in itself, not how urgent it is in your system. When ranking, ask three things in order: is someone already exploiting it out there, does your service actually execute that code, and can outside input reach it? AI can gather these three pieces of evidence for each alert, but deciding which one can be closed remains a human responsibility.
The score says how bad a hit would be, not whether you’ll be hit
The score most scanners report comes from CVSS, the Common Vulnerability Scoring System, maintained by FIRST, an international association of security incident response teams. FIRST’s official specification is clear: the score indicates a vulnerability’s severity relative to other vulnerabilities; assessing risk for your own organization requires adding your own context beyond the score.
In other words, 9.8 says “if this hits, the consequences are severe.” It doesn’t say “you will be hit.” The same vulnerability in a test package that never runs and behind a public entry point has completely different urgency, yet the score is identical.
Answer three questions in order
One: is someone already exploiting it? The US Cybersecurity and Infrastructure Security Agency (CISA) maintains the Known Exploited Vulnerabilities catalog (KEV), which lists vulnerabilities confirmed to be exploited in real attacks, and recommends that organizations use it as one input for prioritizing fixes. A vulnerability on this list doesn’t need to wait for complete evidence before being escalated.
Two: does your service execute that code? A vulnerable package appearing in the dependency list doesn’t mean the service calls the flawed function at runtime. Packages used only in development or testing, or modules that are never called, aren’t on an execution path, so urgency is much lower. This requires looking at the code and actual execution records, not just the package list.
Three: can outside input reach it? Being executed isn’t enough; it also matters who can send data into that code. Public website visitors, low-privilege accounts, and uploaded files are all outside input. Code that only reads fixed internal configuration files has far less chance of being exploited.
Anything that answers “yes” to all three goes to the front. Anything you can’t answer gets recorded as “to verify,” with who will check it, how, and by when, not treated as “fine.” Moving an item down also requires reproducible evidence, such as the code location or an execution trace, not just the tool failing to report more.
AI gathers evidence, people decide what to close
AI is well suited to a first pass: reading the dependency list, searching the code for calls to the flawed function, checking against KEV, finding which entry points accept outside data, and writing an evidence card for each alert that separates “what the tool said,” “what the code shows,” and “what’s still unconfirmed.”
But “this won’t be executed, so we can close it” is a judgment that a future code change can overturn. Closing an alert or lowering its priority should happen after the service owner confirms, with conditions for rechecking written down, such as when a new entry point is added, the architecture changes, or a version is upgraded. Whether an AI-generated fix can go live once the order is set is a separate question; see AI Can Write Security Patches; Whether They Ship Depends on Whether You Can Roll Back.
Three questions take longer than a score
These three questions are closer to real risk than the score, but they take more time. You can’t trace execution paths for all 300 alerts, so do a rough filter first with KEV and “is it behind a public entry point,” then dig into the few that remain.
CISA has also published a decision method called SSVC, which sorts vulnerabilities into handling tiers based on conditions such as exploitation status, technical impact, and importance to the mission. It’s a useful reference for teams that want to make this judgment a formal part of their process. When container image scans produce especially many alerts, pair this with An AI Container Scanner Draws the Line Itself: Mechanical Edits Can Be Automatic, Base Image Changes Need a Person.
As a next step, pick five alerts from the same service, deliberately including a high score that may never execute, an average score behind a public entry point, and one listed in KEV. Re-rank them with the three questions, then compare against the original score order and see which ones moved.
AI handoff card
Our security scan delivered a large batch of vulnerability alerts, and I want to rank them by real urgency rather than by score alone.
The method comes from this article: https://boosterminiclass.com/en/posts/ai-vulnerability-evidence-card-prioritization/
Its view: a scan score measures how severe a vulnerability is in itself, not how urgent it is in this system. Ask in order: is someone already exploiting it (for example, listed in CISA KEV), does the service actually execute that code, and can outside input reach it. Anything that can't be answered is recorded as to verify, not treated as fine.

Review, read-only, only the code, dependency lists, scan reports, and execution records I've authorized. Don't modify files, settings, or tickets, and don't close any alert.
1. Pick at most five alerts from the scan results and list for each: vulnerability ID, package and version, scan score;
2. Answer the three questions for each, with direct evidence for every answer (file path and line number, report item, or the read-only command you ran and its output): is it in KEV, does the service execute the flawed code, which outside inputs can reach it;
3. Separate what the tool says, what you confirmed from the code, and inferences that are still unconfirmed;
4. Re-rank based on the three answers, compare with the original score order, and explain which ones moved and why.
Write "to verify" for anything you can't answer, and suggest who should check it and how. Closing alerts, lowering priority, fixing, and deploying are left to the owner.
References
- FIRST official specification: Common Vulnerability Scoring System v4.0 Specification Document — https://www.first.org/cvss/v4.0/specification-document (2023-11-01)
- CISA official catalog: Known Exploited Vulnerabilities Catalog — https://www.cisa.gov/known-exploited-vulnerabilities-catalog [accessed: 2026-10-11]
- CISA: CISA Releases SSVC Methodology to Prioritize Vulnerabilities — https://www.cisa.gov/news-events/alerts/2022/11/10/cisa-releases-ssvc-methodology-prioritize-vulnerabilities (2022-11-10)